Ryzen AI Max+ 395, 128 GB
96 GB of GPU memory in a box this small.
It loads models that a 32 GB card cannot. Rent it for $0.59 an hour, or buy one for $3599.
What is inside
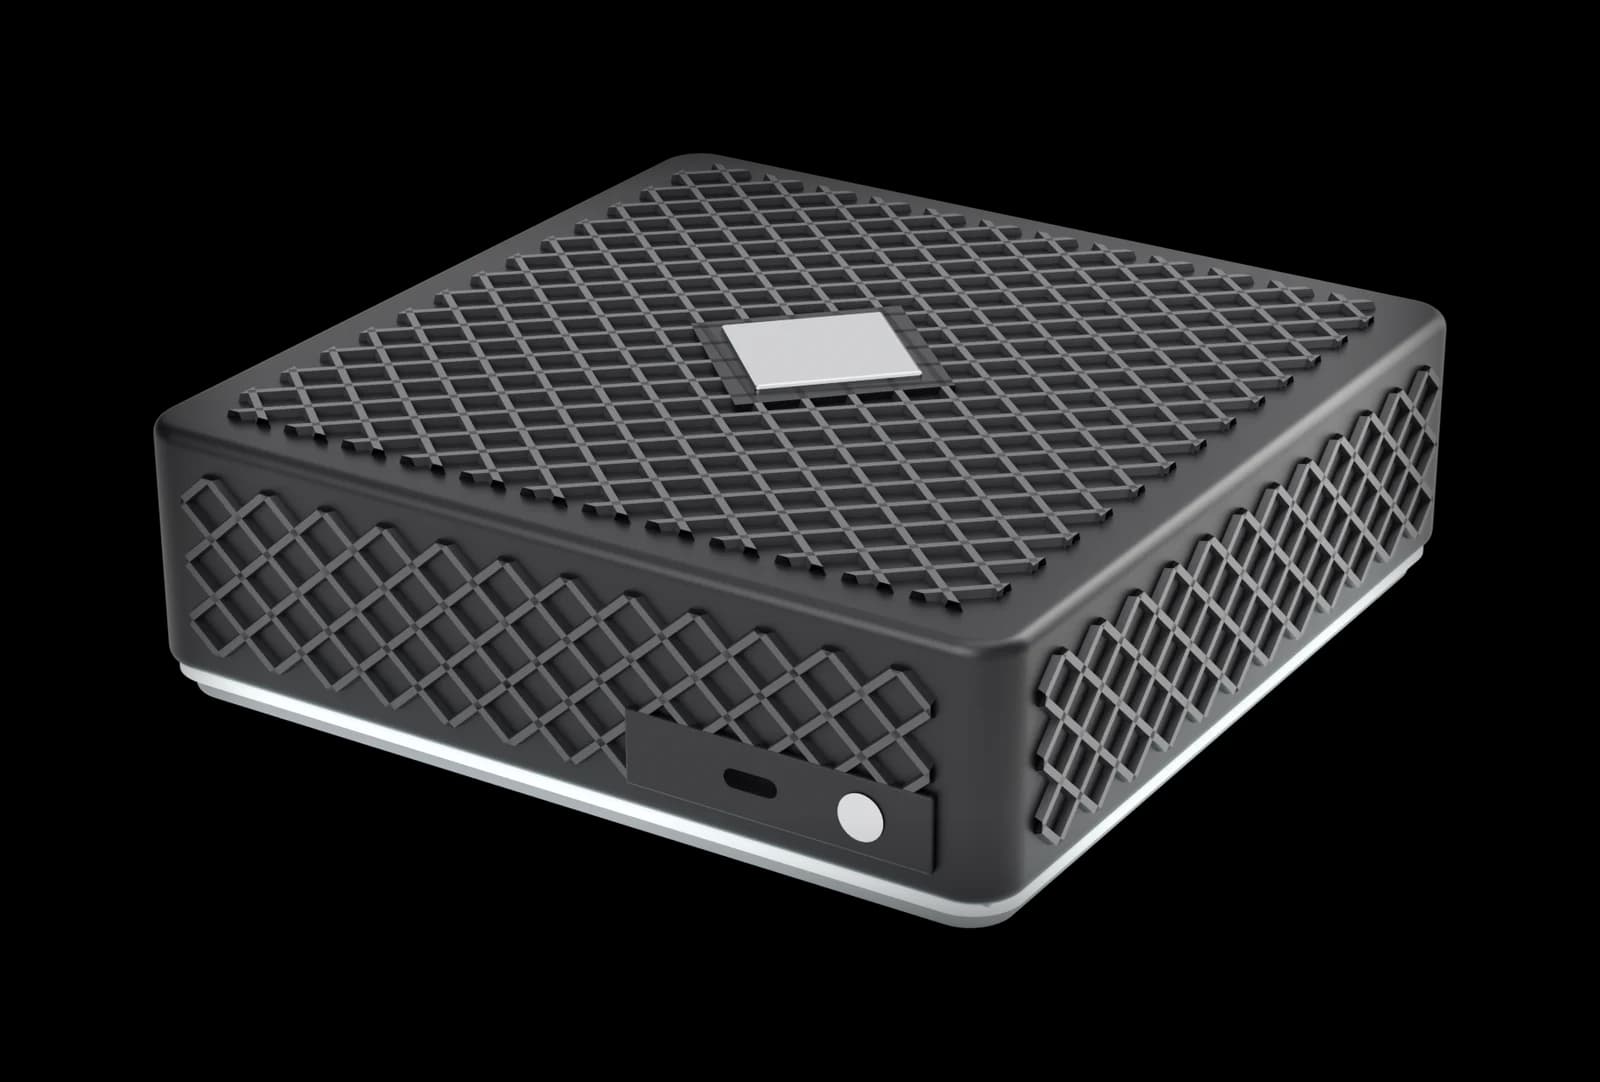
A box you can hold in one hand
Low, square and black. Air moves through the diamond lattice on the top and the sides.
Cooling that holds under load
The GPU sat between 36 and 45 °C during inference runs, and the machine passed a one-hour continuous load test.
One chip does the work
Ryzen AI Max+ 395: sixteen Zen 5 cores and a Radeon 8060S on a single chip under the heatsink.
128 GB of memory around it
LPDDR5X-8533, soldered next to the processor and shared between CPU and GPU. The GPU can address 96 GB of it. A 512 GB NVMe drive sits beside it.
1 of 4. Illustration. The internal layout is simplified.
How the memory is split
CPU and GPU draw from one pool. 64 GB is set aside for the GPU and it can borrow 32 GB more, which leaves 32 GB that is always the system's.
Specification
- Processor
- AMD Ryzen AI Max+ 395
- CPU
- 16 cores, 32 threads (Zen 5)
- GPU
- Radeon 8060S, 40 compute units
- NPU
- XDNA 2
- Memory
- 128 GB LPDDR5X-8533, unified
- Storage
- 512 GB NVMe
- Chassis
- Low square mini PC, diamond-lattice shell
- System
- Ubuntu 24.04, kernel 6.17
- Runtimes
- Mesa 25.2 (RADV), ROCm, llama.cpp with Vulkan and HIP builds
Measured speed
Single runs on this exact machine, generation speed in tokens per second. LM Studio on Windows 11, llama.cpp with ROCm on Ubuntu 24.04.
| Model | Size | Quant | Tokens/s | GPU memory | Runtime |
|---|---|---|---|---|---|
| qwen3.6-35b-a3b | 35B MoE | – | 71.55 | 22.7 GB | LM Studio |
| gpt-oss-20b | 20B | – | 66.45 | 12.8 GB | LM Studio |
| qwen3-coder-next | 80B MoE | – | 57.12 | 47.2 GB | LM Studio |
| qwen3-next-80b | 80B MoE | – | 56.80 | 47.2 GB | LM Studio |
| gpt-oss-120b | 120B MoE | – | 25.96 | 47.3 GB | LM Studio |
| gemma-4-12b | 12B | – | 25.84 | 10.7 GB | LM Studio |
| qwen3.6-27b | 27B dense | Q6_K | 9.29 | 43.4 GB | llama.cpp (ROCm) |
Choose it when
- The model needs more than 32 GB of GPU memory.
- You run mixture-of-experts models: 35B to 80B ran at 57 to 72 tokens per second here.
- You want a long-running private endpoint at a low hourly price.
Pick an RTX card when
- The model fits in 32 GB and you want the most tokens per second.
- You run large dense models: a 27B dense model at Q6_K reached 9.3 tokens per second here.
- Your code needs CUDA. This machine is AMD: Vulkan and ROCm.
Rent it or own it
Rented, you get the whole machine with root over SSH and nobody else on the GPU. Bought, it arrives set up and tested.
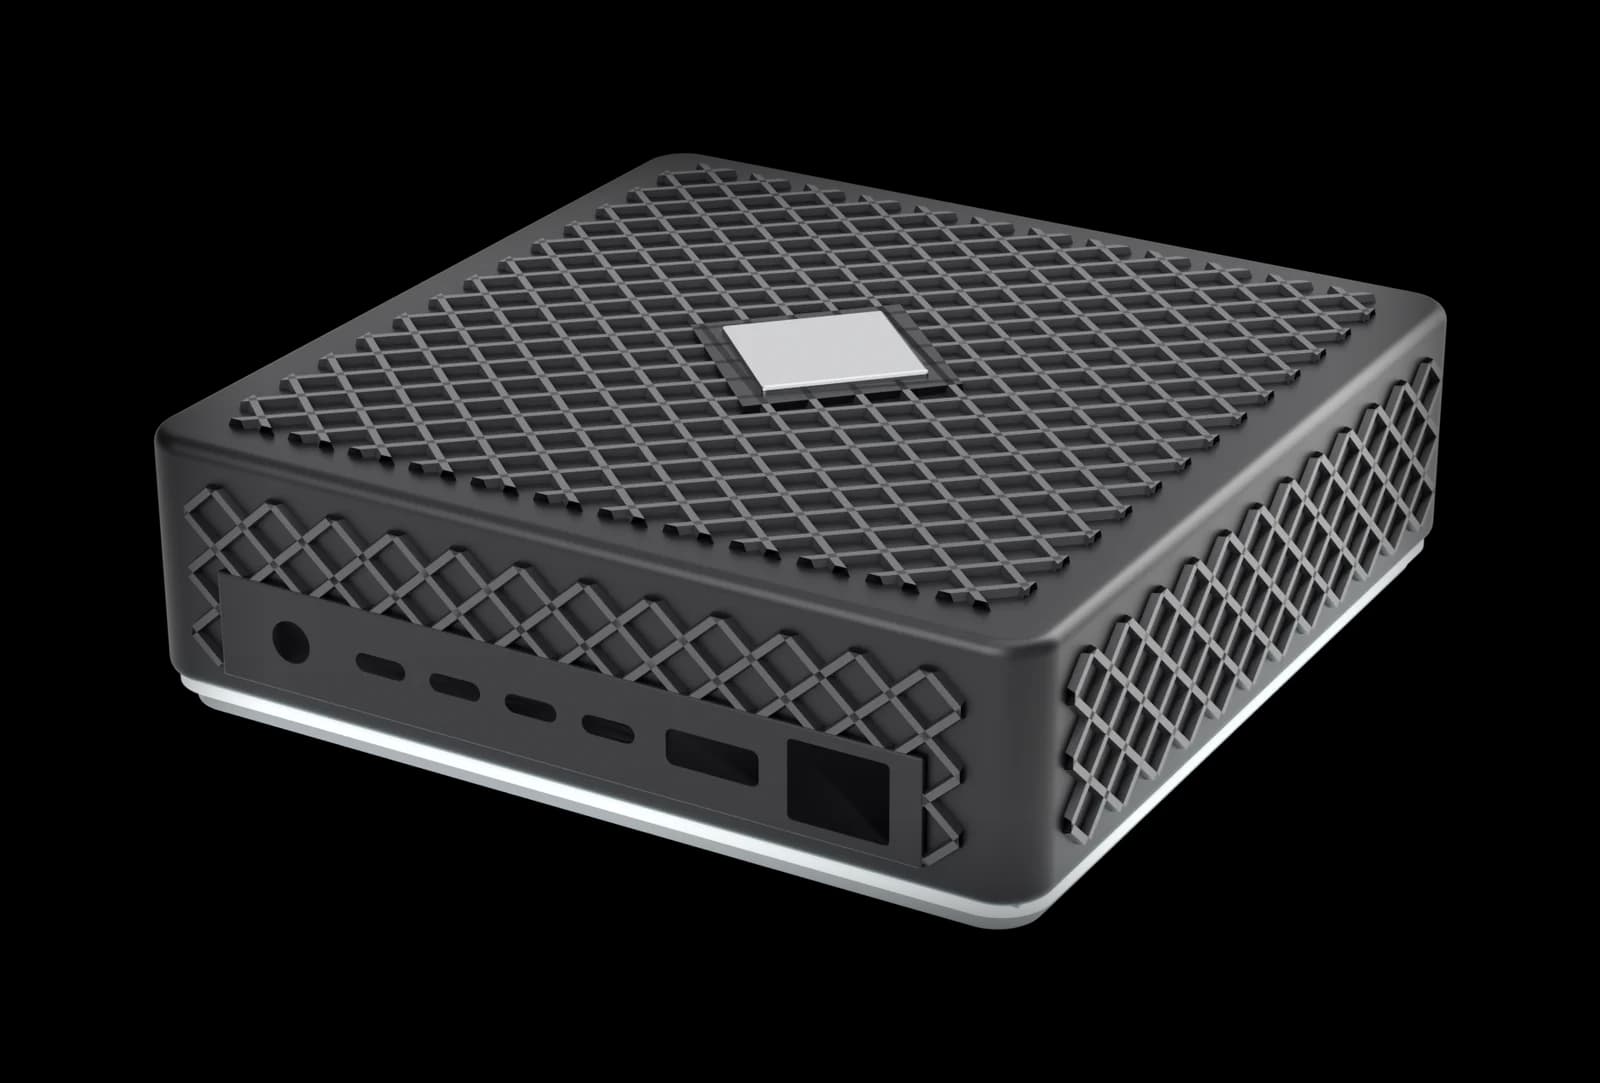
Images are 3D renders. The inside view is a simplified illustration.